Why Leaders Are Moving to AI Augmented Data Management
- Oct 12, 2026
- Isha Taneja
Enterprise data management is breaking under the weight of modern data volumes. Here is why AI augmented data management has become the priority for leaders in 2026.
Enterprise data management is breaking under the weight of modern data volumes. Here is why AI augmented data management has become the priority for leaders in 2026.
Every data leader has sat in a version of the same conversation. A new analytics initiative is on the table. The business case is strong. The urgency is real. And the answer that comes back from the data team is the same one it gave last quarter and the quarter before that. We do not have the capacity to support it right now. The data exists. The infrastructure is running. But the team responsible for managing it is already at full capacity on maintenance, remediation, and reconciliation work that never stops arriving. The gap between what the business needs from its data and what the team can deliver manually is not closing. It is widening.
AI augmented data management is the response to that gap. It is the application of AI and machine learning to the data management workflow so that automated systems handle the volume and the humans handle the judgment. Organizations moving in this direction are not doing so because the technology is new. They are doing so because the alternative, continuing to staff against an exponentially growing data management burden with manual processes, has stopped being viable at the pace modern enterprises need to operate.
The DATAVERSITY Trends in Data Management survey found that 61 percent of data professionals already list data quality as their top challenge, and Gartner projects that through 2026, 60 percent of AI initiatives will be abandoned due to insufficient data quality. The organizations recognizing that manual data management cannot scale to meet the demands of an AI-ready enterprise are making the move to AI augmented data management not as a technology experiment but as a strategic necessity.
The causes companies struggle with enterprise data management have not changed dramatically in the past decade. What has changed is the scale at which those causes now operate and the speed at which their consequences accumulate. Data volumes have grown exponentially while the complexity of the environments those volumes move through has grown in parallel. Source systems multiply, integration requirements expand, and the governance standards required to make data trustworthy across all of those environments become harder to enforce with manual processes applied at the pace and precision that modern enterprise operations require.
The fundamental problem is that traditional data management was designed for a world where data moved more slowly, lived in fewer places, and was consumed primarily by trained analysts rather than by AI agents, automated decision systems, and self-service business users operating without technical oversight. By 2027, Gartner predicts that half of all business decisions will be augmented or automated by AI agents, and those agents are primary consumers of enterprise data alongside human analysts. An enterprise data management approach that was never designed to serve AI agents at that scale cannot simply be maintained more carefully. It needs to be fundamentally rethought.
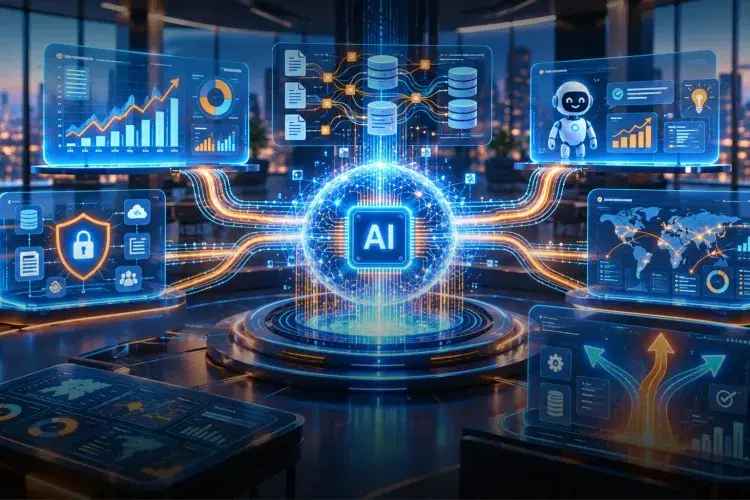
AI augmented data management is not the replacement of data teams with artificial intelligence. It is the application of AI and machine learning to enhance every aspect of the data management workflow so that human expertise is directed toward the work that genuinely requires human judgment rather than consumed by tasks that automation can handle more reliably and at greater speed. The distinction between augmentation and replacement matters because it determines how organizations think about the investment, how data teams respond to it, and what outcomes become realistic within a meaningful timeframe.
In practice, AI augmented data management applies intelligence to the parts of data management that have always been the most time-consuming and the most error-prone when done manually. Metadata tagging and schema generation that previously required manual effort across thousands of fields can be handled automatically with human review at the exception level rather than at every instance. Pipeline recommendations that previously required experienced engineers to diagnose and resolve can be surfaced proactively before they become failures. Query optimization that previously required deep technical knowledge to apply correctly can be automated in ways that improve performance without requiring every change to go through a senior engineer. Enterprise teams using AI-powered data management capabilities save an average of three hours per day per person by eliminating manual data entry and reconciliation tasks, according to Energent research. At an enterprise scale across a data team of ten or twenty people, that recovery of capacity is transformative.
Understanding why AI augmented data management is gaining leadership attention requires being honest about the causes companies struggle with enterprise data management that have resisted every previous attempt at resolution. The four causes that appear most consistently across enterprise data environments are not primarily technical problems. They are structural ones that manual processes cannot resolve at the scale and speed modern enterprises require.
The first is data quality degradation at the source. Data enters the enterprise through dozens of channels simultaneously, and the inconsistencies, duplicates, and formatting errors that accumulate in those entry points compound over time in ways that quarterly data quality audits cannot prevent. The second is governance that exists on paper but not in practice. Policies are documented but not enforced because the enforcement mechanism relies on human review of volumes no team can realistically handle. The third is pipeline fragility that makes data infrastructure brittle in the face of even minor changes to source systems, because the pipelines were built manually to handle specific expected inputs and cannot adapt dynamically to changes they were not designed for. The fourth is the gap between data availability and data trustworthiness, where data is technically present in the environment, but its lineage is unclear, its quality is unverified, and the analysts and AI systems that depend on it cannot know with confidence whether it is safe to act on. Only 4 percent of organizations have achieved high maturity in both data governance and AI governance simultaneously, according to the DATAVERSITY survey, which means the vast majority of enterprises are operating with a structural governance gap that manual processes have not and cannot close.
Next generation data management is not a single technology or a single architectural decision. It is the combination of AI augmentation capabilities applied across the data lifecycle in ways that address the structural causes of data management failure rather than treating their symptoms. The organizations leading this shift in 2026 share a consistent set of capabilities that distinguish their data environments from those still operating on manual processes.
Continuous automated data quality monitoring that identifies and flags issues at the point of entry rather than discovering them during downstream analysis or after they have affected a business decision.
AI-driven metadata management that maintains a living, accurate catalog of what data exists, where it came from, how it has been transformed, and who is accountable for it without requiring manual updates every time the environment changes.
Intelligent pipeline monitoring that detects anomalies, predicts failures before they occur, and recommends corrective actions that engineers can approve and deploy rather than diagnose and build from scratch.
Self-service data access enabled by AI that allows business users to query and consume data without requiring engineering involvement for every request, while maintaining governance controls that prevent ungoverned access.
Automated lineage tracking that provides a complete and auditable record of how data moves through the environment so that every output can be traced to its source and every transformation along the path can be understood and explained
The shift that leaders who have implemented AI augmented data management describe most consistently is not the reduction in cost or the improvement in data quality metrics, though both are real and measurable. It is the change in what the data team is able to do with its time. When the work that previously consumed the majority of engineering capacity is handled by automated systems operating continuously at a scale no team of humans could match, the people in the data organization shift from maintaining the infrastructure to improving it, from reacting to failures to designing against them, and from answering requests they never had time to complete to proactively identifying the data capabilities the business needs before it asks for them. Gartner estimates that by 2026, 90 percent of analytics consumers will become content creators enabled by AI, which means the demand on enterprise data environments is not going to reduce. The only way to meet that demand without continuously expanding the size of data teams is to augment the capability of those teams with AI that handles the volume while the humans handle the judgment.
The organizations moving to AI augmented data management in 2026 are not doing so because the technology has become fashionable. They are doing so because the alternative, continuing to manage data manually at a scale and pace that manual processes cannot support, is producing a compounding gap between the data environment an AI-ready enterprise requires and the one they currently have. That gap is what is causing AI initiatives to stall, analytics programs to produce untrustworthy outputs, and data teams to spend their capacity on maintenance rather than on the work that actually advances the business.
The shift to AI augmented data management is not a decision that becomes easier to make by waiting. Every quarter that an enterprise continues to manage data manually at modern volumes is a quarter in which the quality gap widens, the governance debt grows, and the AI investments sitting on top of that foundation produce less reliable outputs than the business expects. The leaders moving first are not moving because they have more mature data environments than everyone else. Many of them are moving because they recognized early that the maturity gap would never close through manual effort alone. AI augmented data management is the mechanism that makes closing it possible, and 2026 is the year that the business case for making the move has become impossible to defer.
Ready to build an AI augmented data management foundation that your enterprise can actually scale on? Talk to Complere Infosystem today.


Listen in for business strategies and interviews with business experts to help you build a business and a life that you love.
About Us